Translated with AI from the Russian original.
Volcano scheduler considers task priority, computing power, and video memory
Russian infrastructure software developer Orion soft has updated the Nova AI platform for developing and operating AI/ML services. The main change was an automated mechanism for distributing GPUs between different types of workloads.
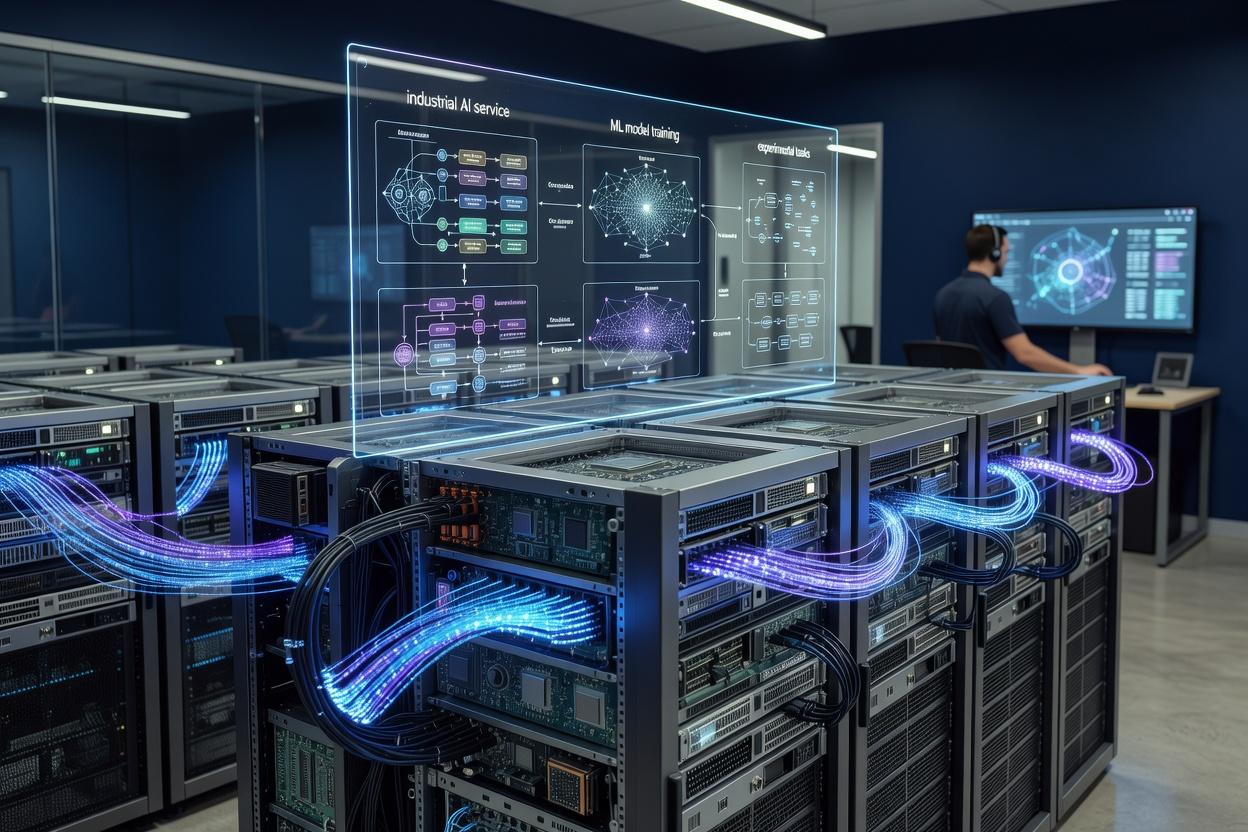
The Volcano scheduler is responsible for managing computing resources. It forms a queue of AI/ML tasks, taking into account their priorities and available capacities. Thanks to this, productive services, model training, and experimental projects can run in a single cluster without constant manual GPU reallocation.
The distribution takes into account the computing power of video cards and the amount of their video memory. Free resources can be directed to development and testing, without reserving them exclusively for a possible increase in load on working services.
The new version also updates the KServe inference backend for TensorFlow, PyTorch, Triton, and vLLM. In addition, SGLang support has been added. The component update should simplify the preparation of models for industrial launch and reduce the amount of manual integration.
Nova AI is a Kubernetes platform for creating and operating AI/ML services on the customer's infrastructure. It combines GPUs into a cluster, distributes computing resources among projects, and provides working environments for ML engineers.