Translated with AI from the Russian original.
The dataset will allow developers to train, test, and improve AI-based anti-fraud systems.
Russian company Smart Engines has released MIDV-DM, a specialized dataset of fake documents for AI developers. The samples included in the set were made using the most common methods of forgery used by fraudsters. It includes 8,000 images with identity documents from Russia, the CIS, and other countries.
As the company emphasized, MIDV-DM became the first public dataset to systematize all the main methods of document manipulation. The set is based on 1,000 images from the MIDV-2020 sample previously published by Smart Engines researchers: samples of the internal passport of the Russian Federation, national passports and ID-cards of Azerbaijan, Latvia, Estonia, Finland and others.
The developers used such manipulations with documents as inserting text fields or photos from a "donor" document, "masking" individual document fields, gluing different fragments into one image, inserting foreign objects - emblems, holograms, and so on.
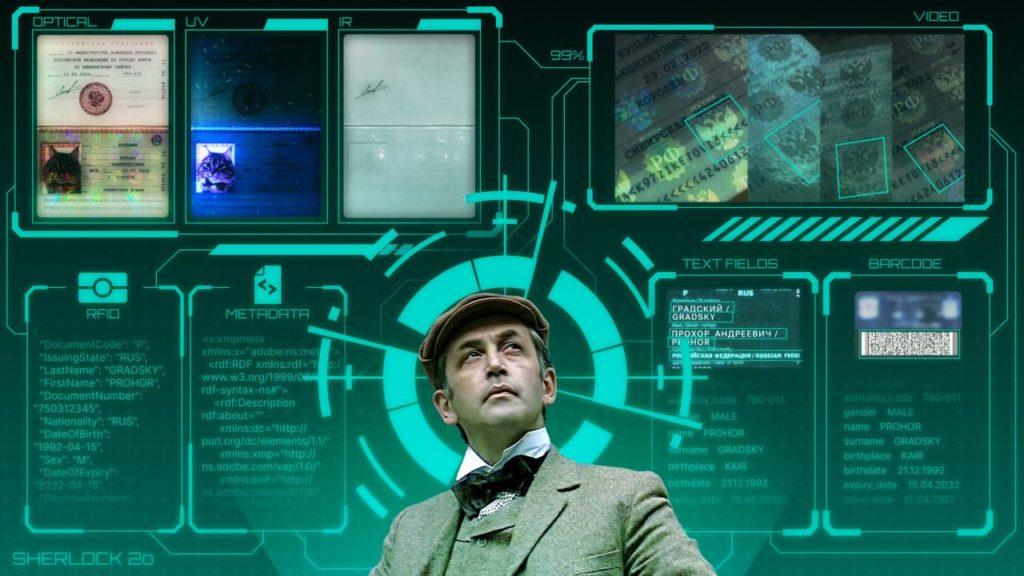
In the future, using MIDV-DM, Smart Engines plans to develop its own anti-fraud system "Sherlock 2o" - a multimodal AI model capable of simultaneously working with images of documents from the optical, ultraviolet and infrared spectra, text fields, NFC-chip data, barcodes, metadata and signatures. In total, the system checks the authenticity of a document against 600 parameters.