Translated with AI from the Russian original.
According to the developers, the solution allows for a fourfold increase in the number of concurrently served users without increasing GPU computing power
Tantor Labs and Botsman platform developer, both part of Astra Group, have introduced a software-hardware solution for storing KV-cache of large language models. The technology allows transferring intermediate data from limited GPU video memory to external NVMe drives, reducing the load on accelerators and increasing the efficiency of request processing.
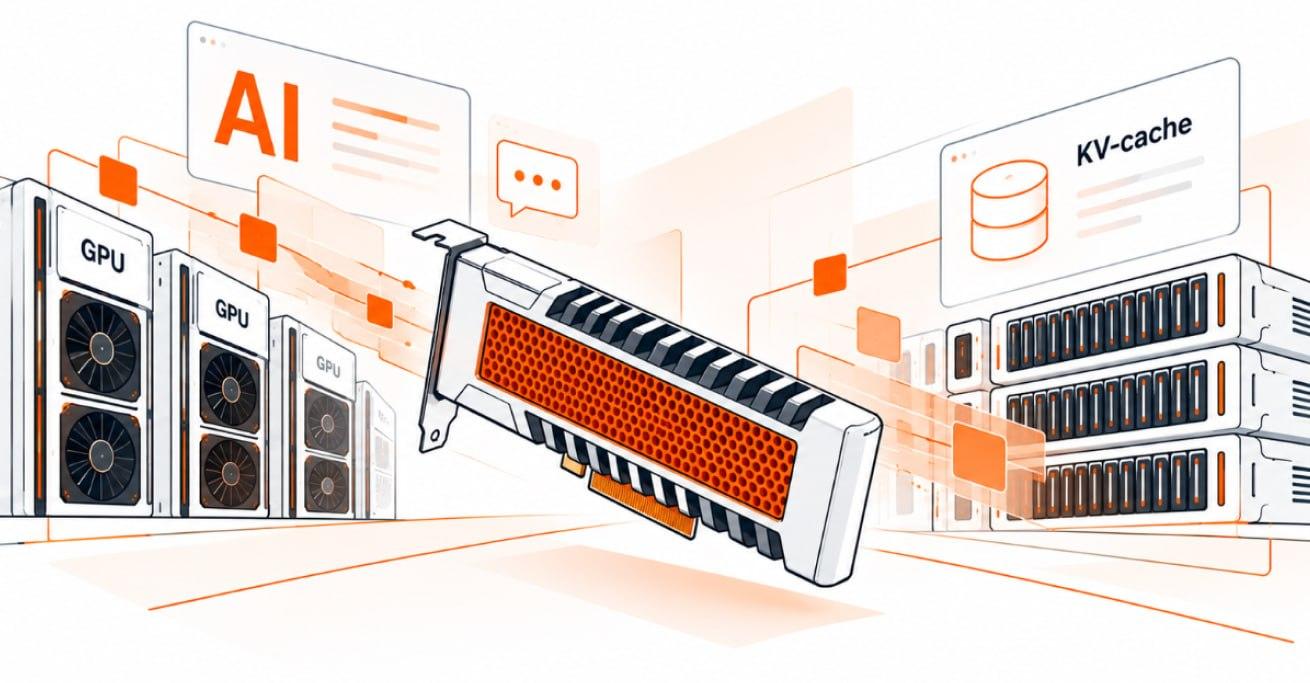
The Tantor Context Memory Storage solution uses a specialized hardware module for fast access to stored data. This allows reusing results from previous computations, reducing latency, and serving more users without a proportional increase in the number of GPUs.
According to the developers, tests on identical servers and models showed that the new technology allows for a fourfold increase in the number of concurrently served clients while meeting specified latency requirements.
The solution supports vLLM, LMCache, and NVIDIA Dynamo environments, as well as Nvidia, AMD, and several Chinese manufacturers' accelerators. Access to context memory is organized via NVMe storage using RDMA and 400 GbE network adapters.
Technology management is integrated into the Botsman platform, which provides deployment and scaling of AI models, distribution of computing resources, and infrastructure monitoring. The joint development is intended for corporate AI services that need to increase load without a comparable increase in computing equipment costs.